Introduction
Machine learning models are only as good as the data used to train them. When that data arrives unlabeled or inconsistently labeled, teams spend months tuning model architecture when the real problem sits upstream in the training set.
According to Grand View Research, the global data collection and labeling market is projected to grow at a compound annual rate of 28.4% between 2025 and 2030, and much of that demand comes from organizations that chose not to build labeling capacity internally.
The hard part is not deciding to outsource but is knowing what a fair price looks like, how to tell a capable vendor from a confident one, and what to put in the contract so quality problems surface before they reach your model.

What is Data Labeling
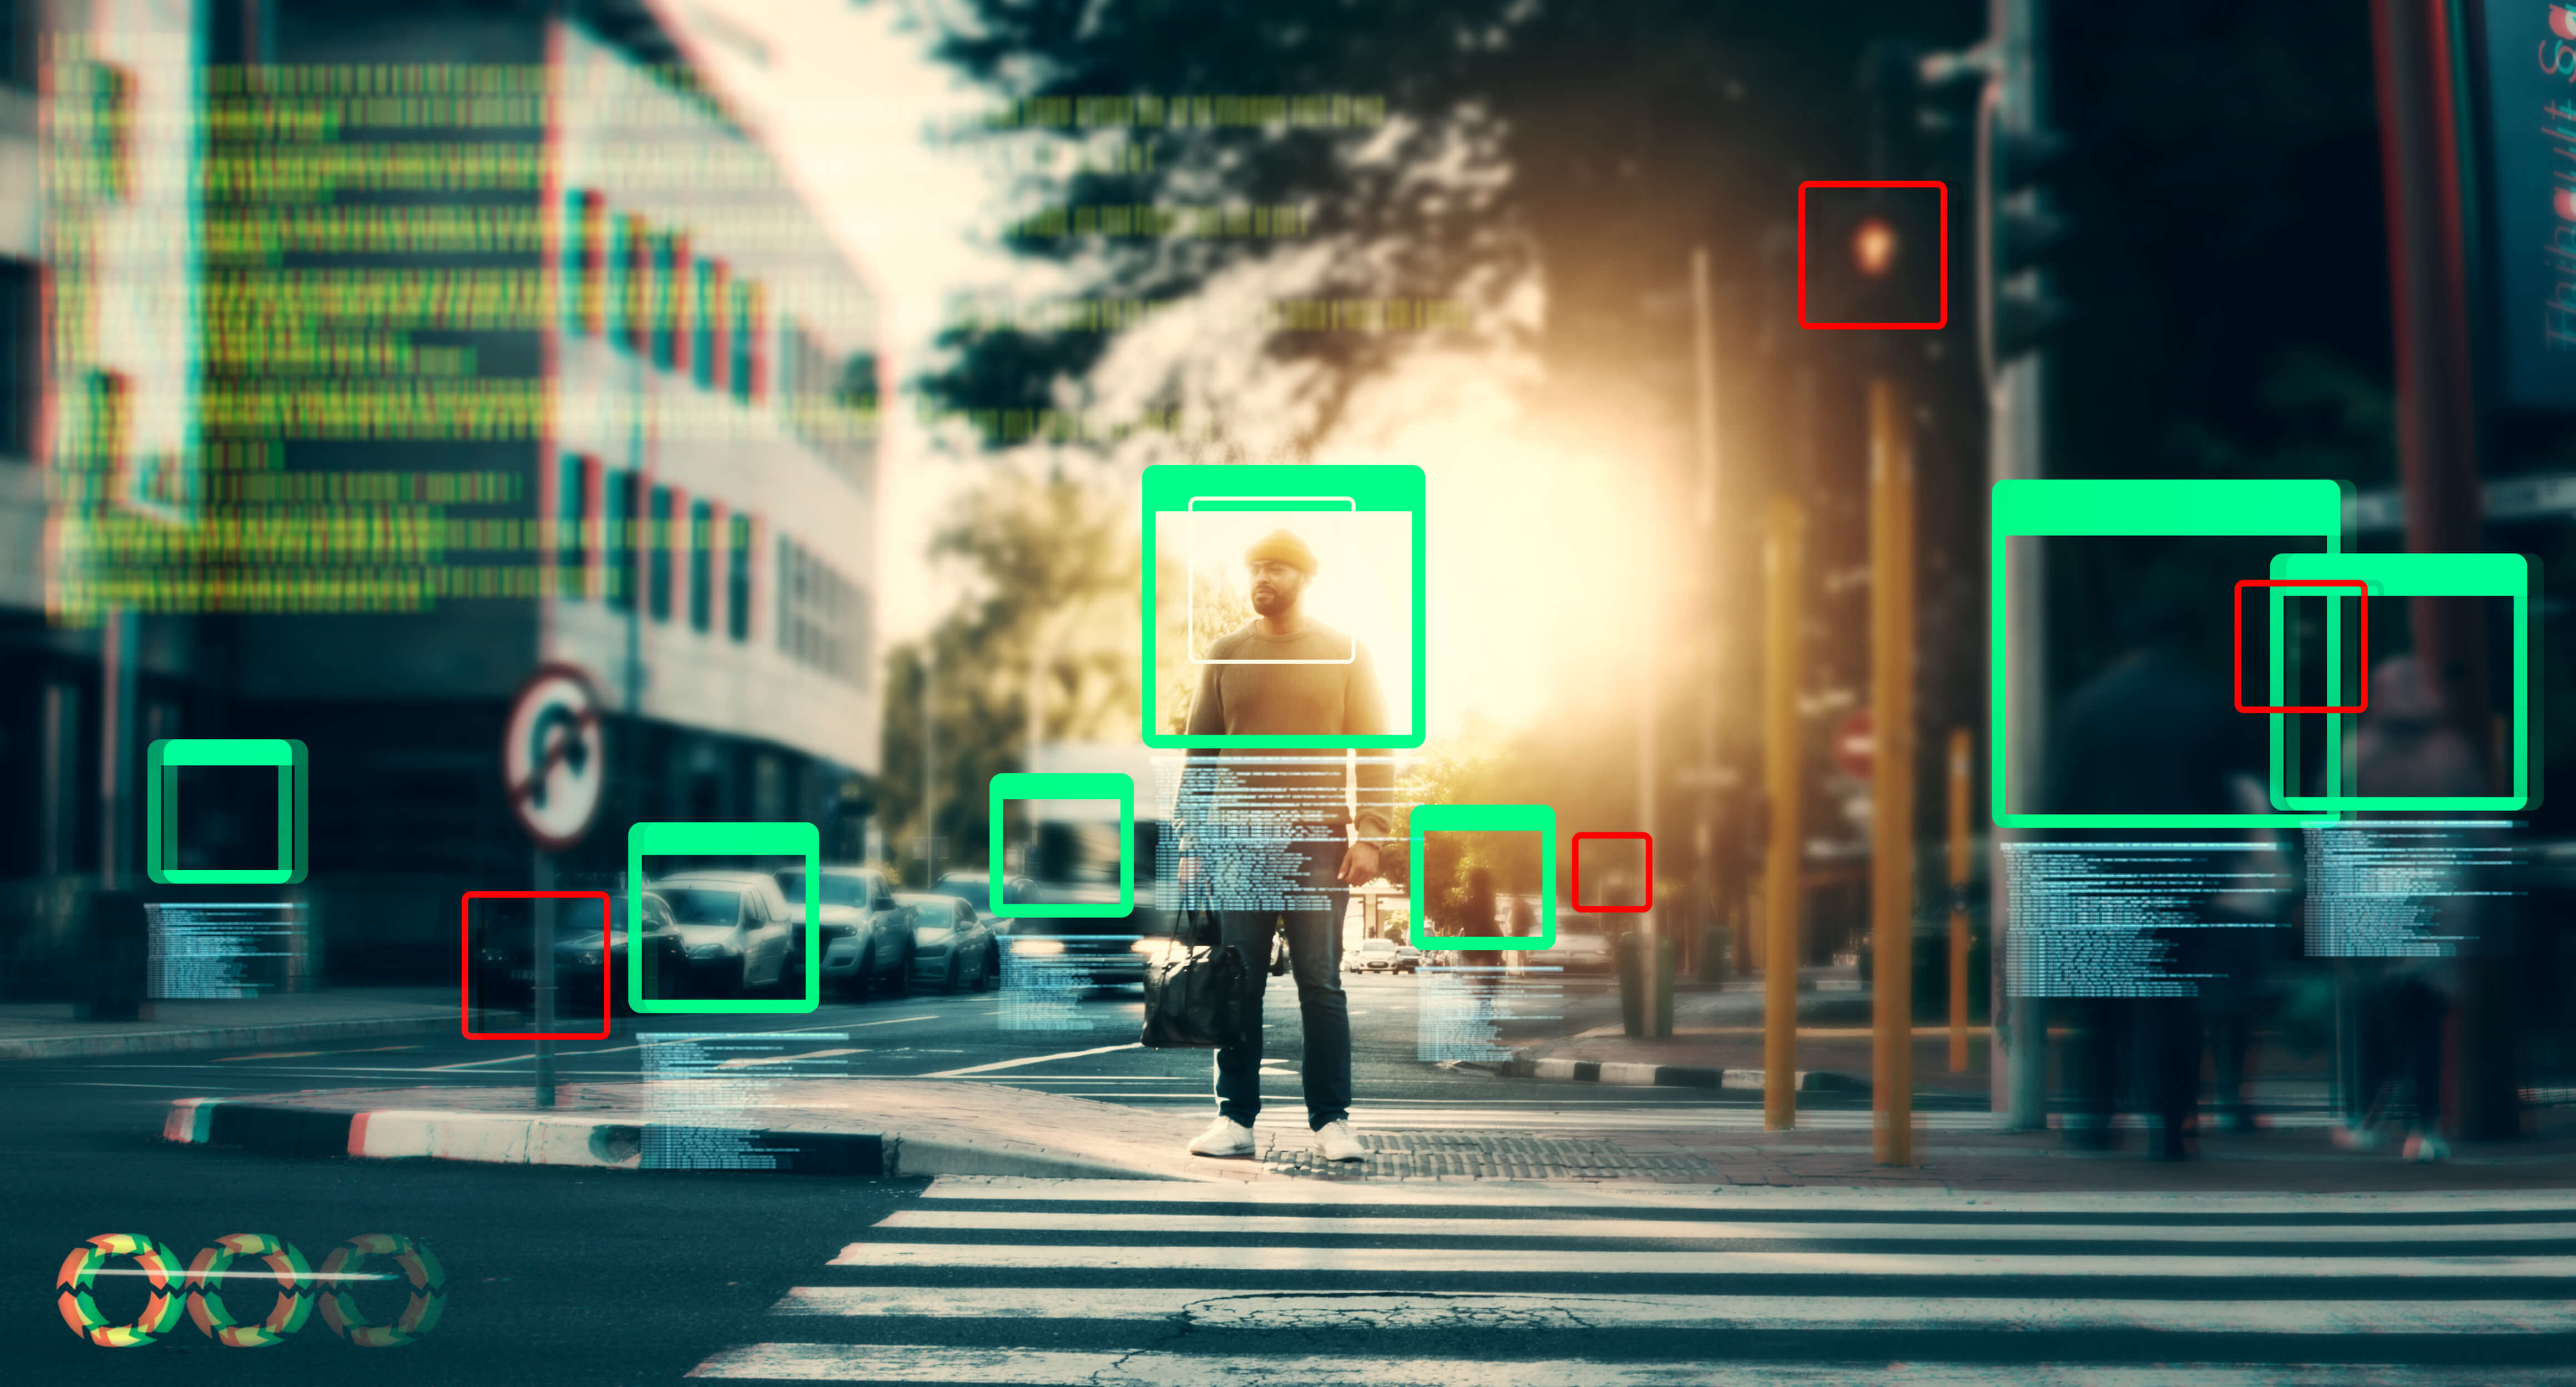
Data labeling is the process of attaching structured annotations to raw data so a machine learning model can learn the relationship between an input and its intended output.
A labeled dataset tells the model that a region of an image is a pedestrian, that a phrase in a contract is a payment term, or that a segment of audio is a specific speaker.
Most production pipelines now use AI-assisted labeling, where a model produces a first pass and human reviewers correct and approve it. That changes the cost structure but not the requirement, since a person still decides whether the label is right.
Requirements differ substantially by data type, and those differences drive price and vendor fit more than anything else in a project scope.
Bounding boxes and text classification are close to commodity work. Pixel-level segmentation, multi-speaker audio, and clinical imaging are not.
For a breakdown of annotation types, see our guide to data annotation.
Should You Outsource Data Labeling or Build an In-House Team?
Outsource when labeling volume is variable, which describes most AI programs before a model reaches production. Build in-house when volume is continuous, the taxonomy is stable, and the data cannot leave your environment. The decision turns on those two variables more than on cost per label.
| In-house | Outsourced | |
|---|---|---|
| Cost behaviour | Fixed. Salaries, tooling, and management continue through idle periods. | Variable. You pay for output, though at very high sustained volume an internal team can win on unit economics. |
| Capacity | Fixed. A volume spike either delays the project or degrades quality. | Elastic. Absorbs a swing from 200,000 labels one quarter to 15,000 the next, but new annotators need onboarding on your taxonomy. |
| Specialist access | Limited to whoever you can hire locally. | Credentialed clinical, legal, and multilingual reviewers on demand, priced in a higher tier. |
| Ramp time | Two to three weeks per annotator at reduced output, paid for. | Absorbed by the vendor, if they work from your guidelines. |
| Quality control | Your standards, your reviewers, direct feedback loops. | Contractual. Only as good as the thresholds you write in. |
| Supporting functions | You need MLOps support and domain reviewers, not just annotators. | Included in a managed engagement. |
Two points the table understates. You keep full IP control in-house, while an outsourced arrangement governs it by contract, so read the assignment clause. And security is often cited as the reason to stay in-house, but a vendor who prioritizes security can be a good choice. Ruling out outsourcing on security grounds alone is usually the wrong call.
How Much Does It Cost to Outsource Data Labeling?
Outsourced data labeling is usually priced per unit, per hour, or per project. As of 2026, public vendor rate cards and industry overviews show a very wide spread: from low single‑digit cents per image for simple classification to tens or over $100 per image for complex medical or satellite segmentation, with many standard computer‑vision detection work in the cents‑to‑low‑dollar range per object.
Four factors drive that spread more than volume: annotation complexity, domain expertise, the quality threshold you enforce, and the vendor's compliance controls. The table below is a planning aid, not a quote.
Table: Illustrative 2026 pricing bands for outsourced data labeling (directional only)
These ranges are compiled from publicly available vendor rate cards and industry overviews published in 2025–2026. They are intended for budget sizing and sanity checks, not as quotes. Actual prices vary widely with annotation complexity, domain expertise, QA design, minimum volumes, platform fees, data sensitivity, and geography.
| Annotation task | Pricing unit | Illustrative 2026 range* |
|---|---|---|
| Image classification, single label | per image | ~$0.01 to ~$0.15 |
| Bounding box, object detection | per object | ~$0.02 to ~$0.90 |
| Polygon or instance segmentation | per object / per mask | ~$0.10 to ~$3.00+ |
| Semantic segmentation, complex scene (e.g., medical, satellite) | per image | ~$10 to >$100 |
| Text classification or named entity recognition | per record / per entity | ~$0.02 to ~$0.25 |
| Medical imaging or 3D LiDAR cuboid | per object | ~$0.50 to ~$7.00+ |
Directional ranges based on selected public vendor rate cards and industry overviews from 2025–2026; not a substitute for a scoped quote.
The gap between a bounding box and a segmentation mask is not incremental; it is often one to two orders of magnitude, so deciding whether your model can train on boxes is worth more than any rate negotiation.
The premium on medical and geospatial work reflects the reviewer rather than the tooling. You are paying for a credentialed person's time.
Is outsourcing data labeling cheaper than doing it in‑house?
For variable‑volume projects, outsourcing is often cheaper on total cost, because in‑house fixed costs continue during periods with no labeling work. For continuous, high‑volume labeling of one stable data type, the calculation can reverse.
The comparison most buyers get wrong is scoping the in‑house side as salaries only. Run both columns with your own inputs before requesting quotes. This is a budgeting framework, not a projection.
| Cost line | In‑house | Outsourced |
|---|---|---|
| Annotator time | Fully loaded rate × hours | In the unit rate |
| QA and review | Reviewer headcount | Only if the contract says so |
| Ramp and training | 2 to 3 weeks at reduced output (varies by task) | Vendor absorbs, if they work from your guidelines |
| Platform licence | Per‑seat or enterprise | Usually included, confirm |
| Management | Engineering manager's time | Vendor PM, confirm if billed |
| Idle capacity | Full carrying cost | None |
The comparison turns on the two lines buyers omit: ramp time and idle capacity. If your need is a single push with nothing behind it, the in‑house column carries months of cost for weeks of work.
What are the hidden costs of data labeling outsourcing?
The quoted rate typically excludes several categories that surface after signing.
- Rework. If a batch fails your threshold, who pays to fix it? Rework billed separately raises your real cost per usable label above the quote.
- Guideline development. Some vendors charge for taxonomy design, or include it and bill for revisions once the project is live.
- Minimum order volumes. A low rate attached to a 50,000‑unit minimum is not a low rate for a 10,000‑unit project.
- Platform and API fees. Whether tooling, API access, and data export are bundled.
- Compliance overhead. On‑premise labeling, VDI, and restricted‑geography delivery carry legitimate premiums. They belong in the quote, not a change order.
The pricing model changes vendor behaviour, which makes it a quality decision as much as a commercial one.
| Model | Best suited to | Primary risk | Contract safeguard |
|---|---|---|---|
| Per label | High‑volume, structurally consistent tasks. Bounding boxes, classification, tagging. | Speed is incentivised over accuracy. A related failure is label inflation, where ambiguous objects get over‑labeled because each label bills. | Accuracy floor, an IAA threshold, and rework included in the quoted rate. |
| Per hour | Complex tasks where time per item varies. Medical segmentation, multi‑step NLP, sensor fusion. | Throughput is not guaranteed and cost is open‑ended. | Throughput expectations, a not‑to‑exceed cap per batch, annotator‑level visibility. |
| Per project | Fixed‑scope deliverables with a taxonomy agreed in advance. | Scope changes trigger renegotiation, so vendors price conservatively. | Written change‑control process and a clear definition of scope change. |
Never accept a per‑label rate without a written accuracy threshold attached. A rate quoted without a quality floor is a rate for labels, not for usable training data.
Want a scoped estimate rather than a range? Talk to an AI expert at Tech.us about your data type, volume, and compliance requirements.
How to Choose the Best Data Labeling Outsourcing Partner
Evaluating a data labeling vendor comes down to four questions: whether they have worked on your data type before, how they prove accuracy at the batch level, what happens when a batch fails, and whether their security posture matches your regulatory obligations. Price is the last filter, not the first. Define scope first, because vendors price ambiguity conservatively.
What is inter-annotator agreement, and what score is acceptable?
Inter-annotator agreement (IAA) measures how consistently two or more annotators apply the same label to the same item. It is the most useful quality metric a buyer can ask for, because unlike a vendor-reported accuracy percentage, it can be independently recomputed from delivered data.
The common statistics are Cohen's kappa (1960) for two annotators, Fleiss' kappa (1971) for three or more, and Krippendorff's alpha for mixed data. Each corrects for chance agreement, which is what makes them more informative than percent agreement. The standard scale comes from Landis and Koch (1977):
| Kappa | Interpretation |
|---|---|
| 0.00 to 0.20 | Slight |
| 0.21 to 0.40 | Fair |
| 0.41 to 0.60 | Moderate |
| 0.61 to 0.80 | Substantial |
| 0.81 to 1.00 | Almost perfect |
In production settings, teams often set stricter thresholds than academic papers. Recent practitioner guidance treats a kappa below 0.80 on subjective tasks such as sentiment or intent as a risk signal, on the reasoning that a model trained on labels two humans disagree about one time in five inherits that ambiguity.
Two caveats matter, and a vendor who raises them unprompted is worth taking seriously. Consistent annotators are not the same as accurate ones, since two reviewers who both default to the same answer produce a high kappa and a useless dataset.
And kappa behaves poorly on imbalanced label distributions, where percent agreement above 90% can still return a low score. For skewed data, ask for Gwet's AC1 alongside kappa.
What Should a Data Labeling SLA Include?
An enforceable data labeling SLA specifies four things: how the label taxonomy is governed, what accuracy threshold a batch must clear and how it is measured, whether errors trace to individual annotators, and what happens when a batch fails. Turnaround and unit price belong in the contract too, but they are not what protects your training data. The question to ask is not how fast a vendor can annotate. It is how they prove accuracy at the batch level.
Taxonomy governance
The label set is the specification, and it changes mid-project. State who owns it and how changes are approved. Require version control on the guidelines, with each batch tagged to the version it was labeled under.
An accuracy floor with a stated measurement method
"99% accuracy" means nothing until the contract states what is measured, against what reference, on what sample size, and computed by whom. If the vendor computes it on their own sample, you have a self-graded exam.
Annotator-level error traceability
Aggregate accuracy tells you a batch has a problem. Traceability tells you where it came from, and failures are rarely evenly distributed. They concentrate in a few reviewers or one ambiguous class. Vendors with mature quality systems can isolate this. Vendors reselling crowd capacity often cannot.
A remediation path for failed batches
Specify the correction window, who pays for rework, and the escalation path if a second attempt also fails. Rework included in the quoted rate differs meaningfully from rework billed separately, and it is worth a higher headline rate.
How do you know if your annotators are using AI instead of doing the work?
You detect model-generated labels the same way you detect any quality problem, through a private gold set and per-class agreement analysis, because LLM-generated labels fail in a recognizable pattern. They are highly consistent, plausible, and systematically wrong on edge cases.
The signature is a distribution that is too clean. Human annotators disagree on genuinely ambiguous items, and that disagreement is informative. Put ambiguous items in your gold set deliberately, and where AI-assisted labeling is part of the agreed workflow, require that human review be verifiable rather than assumed.
What are the Different Types of Data Labeling Outsourcing Models
Four models dominate. The right one depends on data sensitivity, task complexity, and volume stability.
| Model | How it works | Best for | Main limitation |
|---|---|---|---|
| Crowdsourcing | Tasks distributed to a large worker pool via platforms such as Amazon Mechanical Turk. | High-volume, low-complexity work on non-sensitive data. | Little visibility into who labeled what, and no practical way to enforce a security posture. |
| Managed services | One vendor owns the project end to end: sourcing, tooling, guidelines, QA. | Production programs where label quality affects model performance, and regulated data. | Higher unit rate, generally recovered in reduced rework. |
| Dedicated offshore teams | A team assigned exclusively to your account in a lower-cost location. | Long-running programs with sustained volume, where the learning curve pays back. | Fixed monthly commitment, so it suits steady demand rather than bursts. |
| Hybrid AI-assisted | A model pre-labels, humans confirm and correct. Most production labeling works this way. | High-volume work where a reasonably accurate model already exists. | Anchoring. Reviewers accept a suggested label more often than they would produce it independently. |
Ask any vendor using pre-labeling how they control for anchoring. Tech.us operates the managed model, combining AI-assisted pre-labeling with domain reviewers and a defined QA layer.
Making the Decision
The vendor question is usually framed as who is best. A more useful frame is what would have to be true for this to fail, and whether the contract catches it. Three checks separate a program that works from one that produces expensive rework.
Build a private gold standard set before you talk to any vendor. Insist on a paid pilot staffed by the annotators who would run production. Put the accuracy threshold, its measurement method, and the remediation path in writing before the first full batch. Vendors who resist those three are telling you something useful.
Tech.us provides managed data labeling and data annotation services for enterprise AI programs across construction, healthcare, financial services, manufacturing, and logistics. For a quote against your actual data rather than a rate card, talk to an AI expert.
FAQs
Estimate labeled units rather than files, since one image may hold several labeled objects. Multiply by a quoted per-unit rate, then add 15% to 30% for QA, rework, and setup. Validate with a paid pilot first, because pilot throughput is the only reliable input for the final number.
A gold standard dataset is a small sample of items labeled to a known-correct standard by your own domain experts, withheld from the vendor and used to score delivered work. Two hundred to five hundred items is typically enough, weighted toward difficult edge cases.
Expect a measurable threshold rather than a general claim. For objective tasks such as bounding boxes on clear objects, agreement above 95% against a gold set is reasonable. For subjective tasks such as sentiment or intent, inter-annotator agreement is the better metric, and a kappa below 0.80 is generally a risk signal.
Partially. AI-assisted labeling uses a model to generate a first pass that human reviewers confirm or correct. This is standard in production pipelines and substantially cuts cost. Fully automated labeling without human review is not reliable for training data, because model errors on edge cases propagate into the next model.
Continue reading the blog
with a Tech.us subscription
You’re now subscribed!