
Key Takeaways
- Computer vision works by teaching machines to understand visual data the way our brain does. It finds patterns in pixels and builds up to context and meaning.
- The evolution of computer vision moved from hand-coded rules to data-driven deep learning. This shift unlocked more complex, scalable solutions.
- CNNs power most modern vision systems. They use filters to detect edges, textures, and shapes, layer by layer, forming a complete understanding of data.
- Image classification assigns a label to the entire picture. It’s great for simple tasks like “cat vs dog,” but can’t say where the object is.
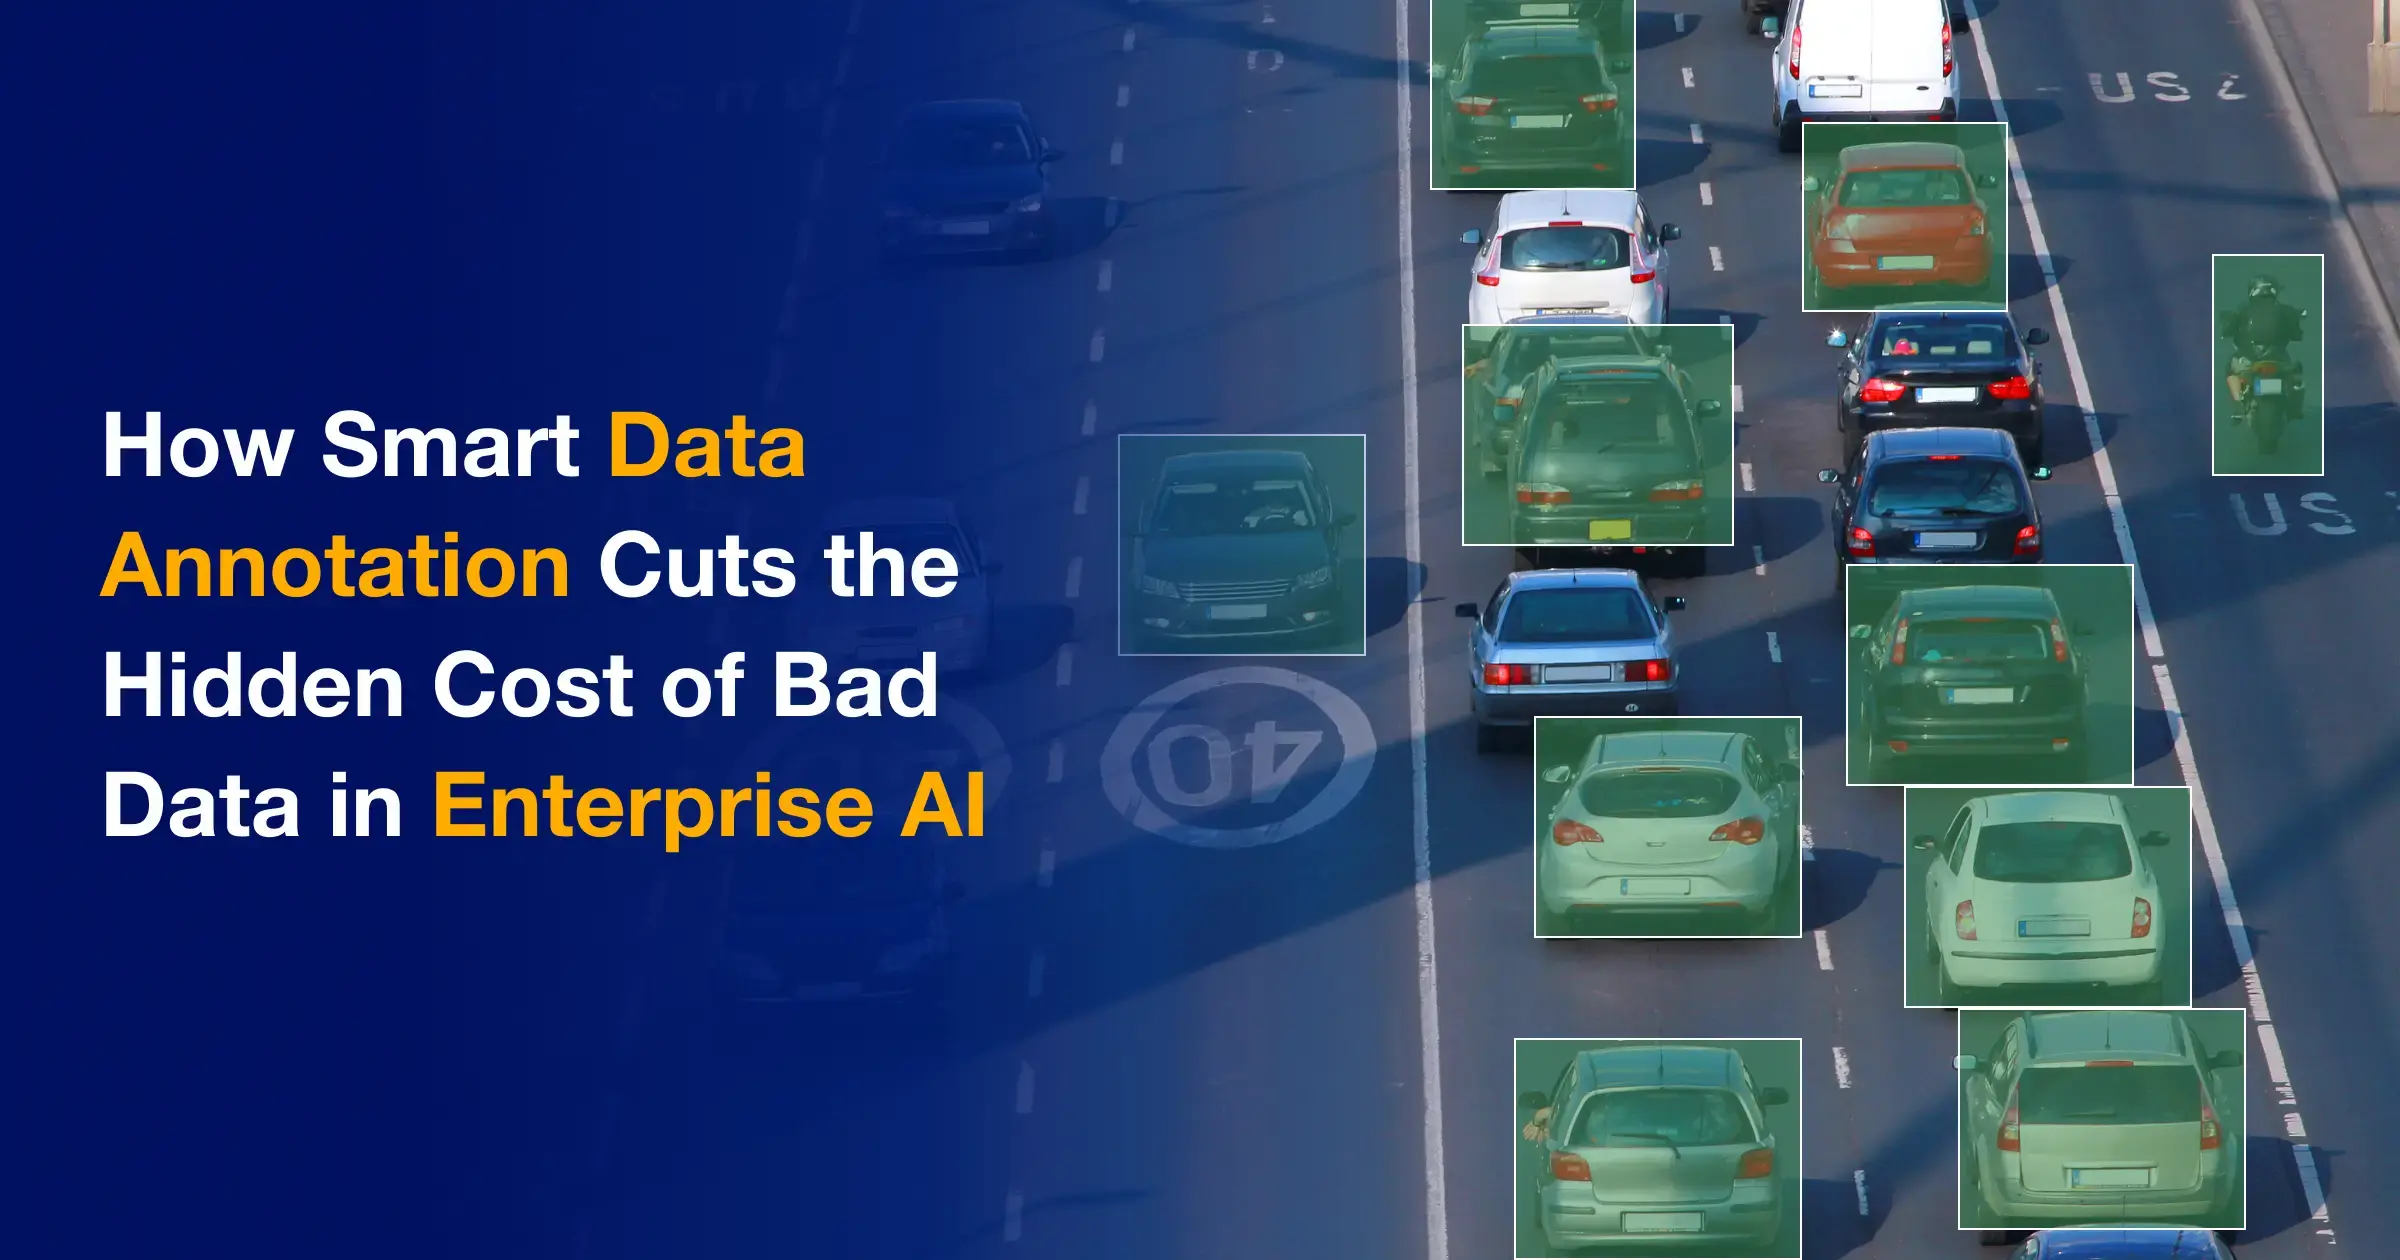
- Object detection goes further. It draws boxes around objects and labels them.
- Semantic segmentation breaks the image into regions by labeling each pixel. It’s precise and used in tasks like autonomous driving or medical scans.
- Instance segmentation separates objects of the same type. Instead of just labeling pixels as “person,” it marks each individual person in the image.
- Feature extraction turns raw images into numbers machines can use. It finds patterns like edges or color blobs and passes them to deeper layers or classifiers.
- Transfer learning saves time and compute. Instead of training from scratch, you start and fine-tune it for your task.
- Real-world applications go beyond theory. It has immense applications for critical industries like healthcare and agriculture.
How Computer Vision is Different from Human Vision
There is a stark difference between how humans perceive visual data and how machines do. Humans use their eyes and brains to make sense of the world. We can even say that we are great at spotting things, recognizing faces, and noticing changes without much effort.
On the other hand, computers work in an entirely different way. They typically look at pixels, tiny dots of color, and then analyze them through numbers and patterns. They don’t “see” like we do. In other words, they don’t picturize things. Instead, they use algorithms to understand what those pixels represent.
What’s impressive is that with the right data and training, a machine can sometimes spot patterns even humans might miss. For example, in medical imaging, AI might find early signs of a disease that even trained doctors could overlook.
The Role of Machine Learning and Neural Networks in Computer Vision
At the heart of modern computer vision lies machine learning, which is how computers learn to improve over time.
Instead of being told what a cat looks like, a computer is shown thousands of images of cats, thanks to data annotation, computers can understand each data.
It then learns what patterns are common in those pictures, which could be like fur, ears, or eyes, and builds its own way of recognizing them.
Neural networks, especially convolutional neural networks (CNNs), the specialized machine learning algorithm types, are the main tools used here. They are designed to work well with images. These networks effortlessly scan images, that too layer by layer, and pick up more detail each time.
This process lets the system learn things like shapes, textures, and the complexities of visual data. Over time, the model gets better at spotting things on its own.
Face unlocks on phones and detecting defects on a product line are some examples of a vast number of applications that this technology has unlocked.
How Computer Vision Works
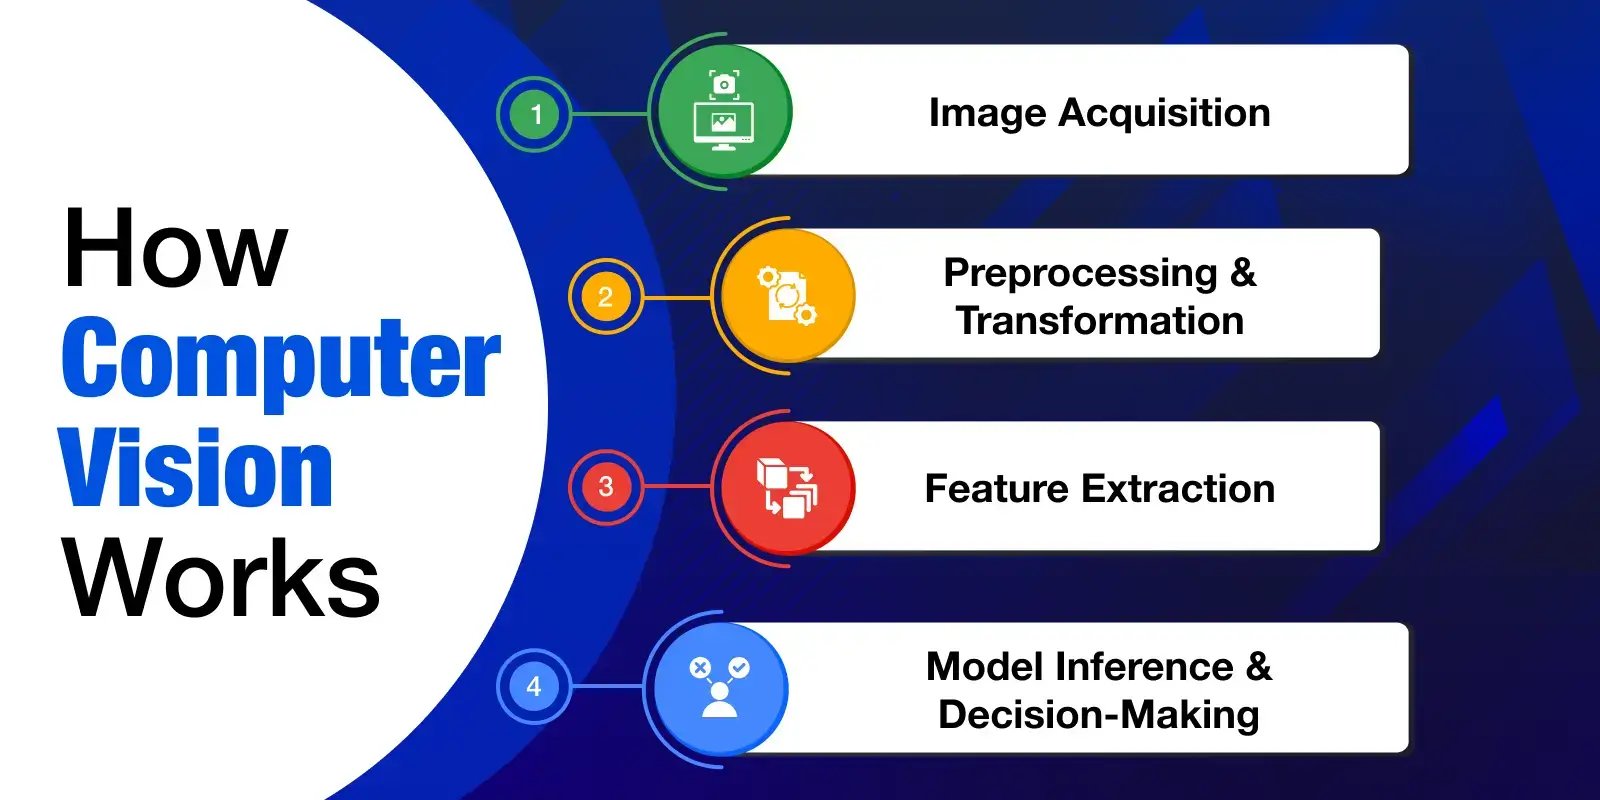
- Image Acquisition
- Preprocessing and Transformation
- Feature Extraction
- Model Inference and Decision-Making
1. Image Acquisition
2. Preprocessing and Transformation
3. Feature Extraction
4. Model Inference and Decision-Making
Traditional vs Deep Learning Pipelines
The Role of Labeled Datasets and Annotations
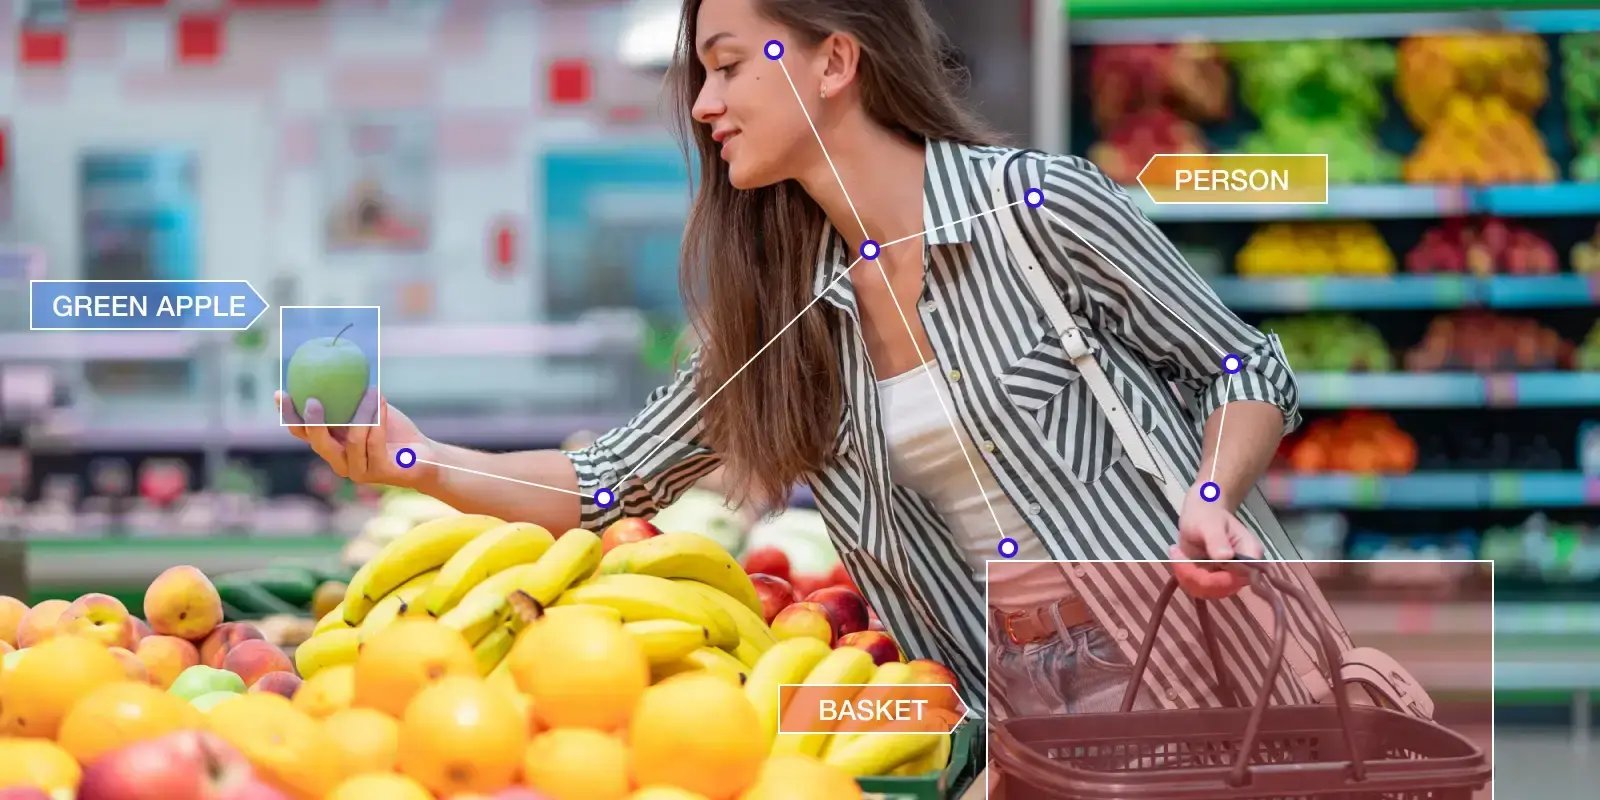
To train these smart systems, we need labeled data. That means images with clear tags or descriptions. This is where data labeling for machine learning and the meticulous process of data annotation come in.
If you want the system to recognize cats, you feed it lots of cat photos. Each one must be labeled: “This is a cat.” Over time, the model learns what a cat looks like.
Sometimes the labeling goes deeper, like for object detection, labels include the exact position of the object inside the image. And, for facial recognition, it could possibly include the meaning of emotions or identity.
This process is called data annotation. It essentially labels data like telling machines what each data means. The more accurate the labels, the better the system learns.
Without labeled data, the system can’t learn much. That’s why good datasets are very important for every successful computer vision project.
Core Capabilities of Computer Vision
Computer vision performs a plethora of tasks and helps machines “visualize” data like images, videos, and other visual inputs. Here are some of its core capabilities.
Object Classification
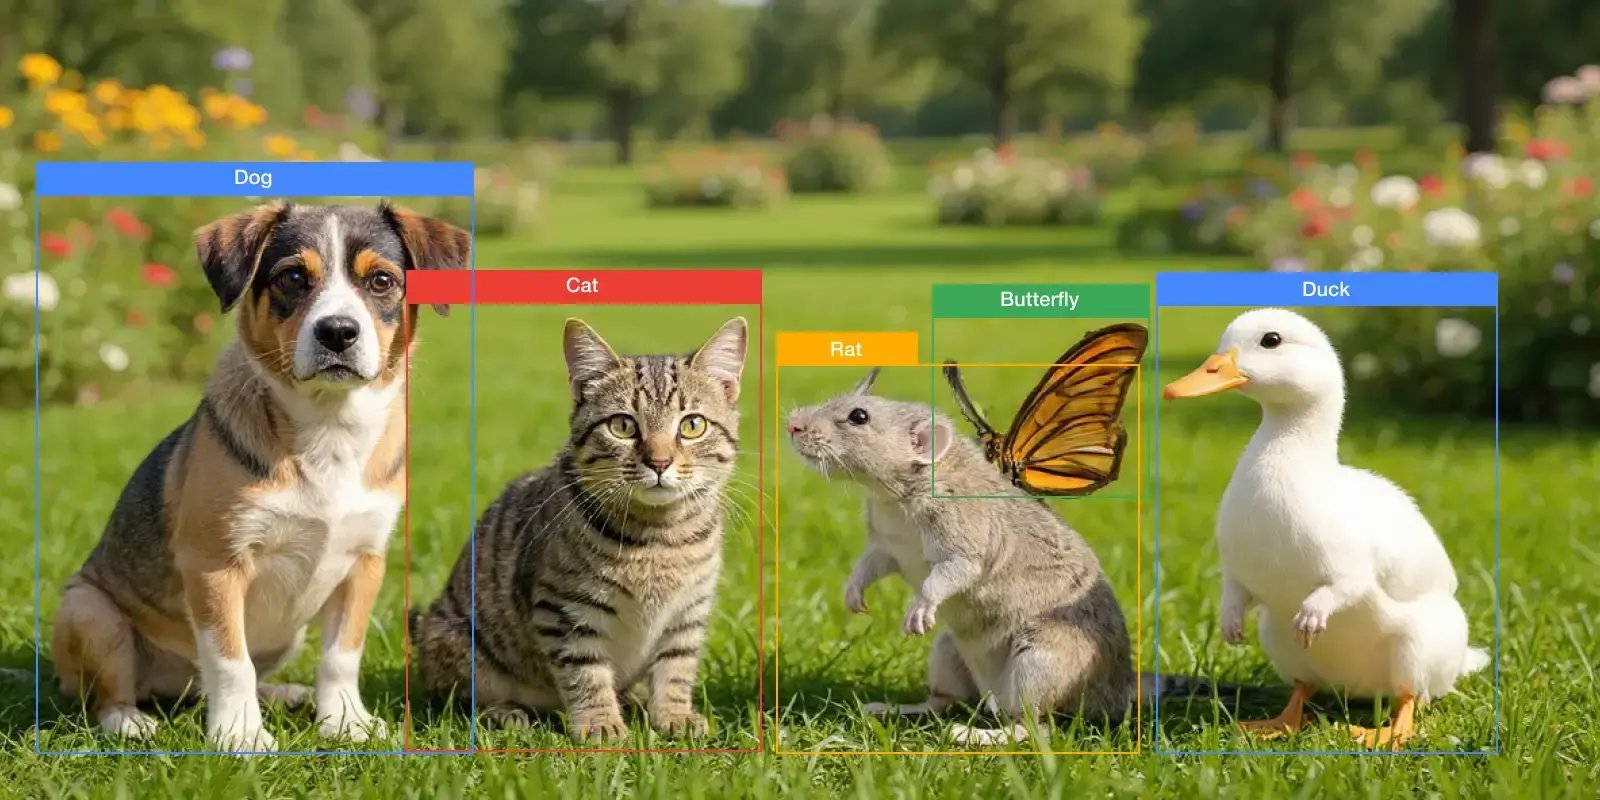
One of the most basic skills that computer vision systems learn is to classify objects. It means the system looks at a visual data, let’s say an image, and decides what are its components. It makes this prediction based on patterns it has learned. If you show it a photo of a cat, and it labels it “cat,” that’s object classification in action.
- Focuses on predicting a single label for the entire image
- Trained using large labeled datasets like ImageNet
- Often the first step before moving to more complex tasks
Object Detection and Recognition
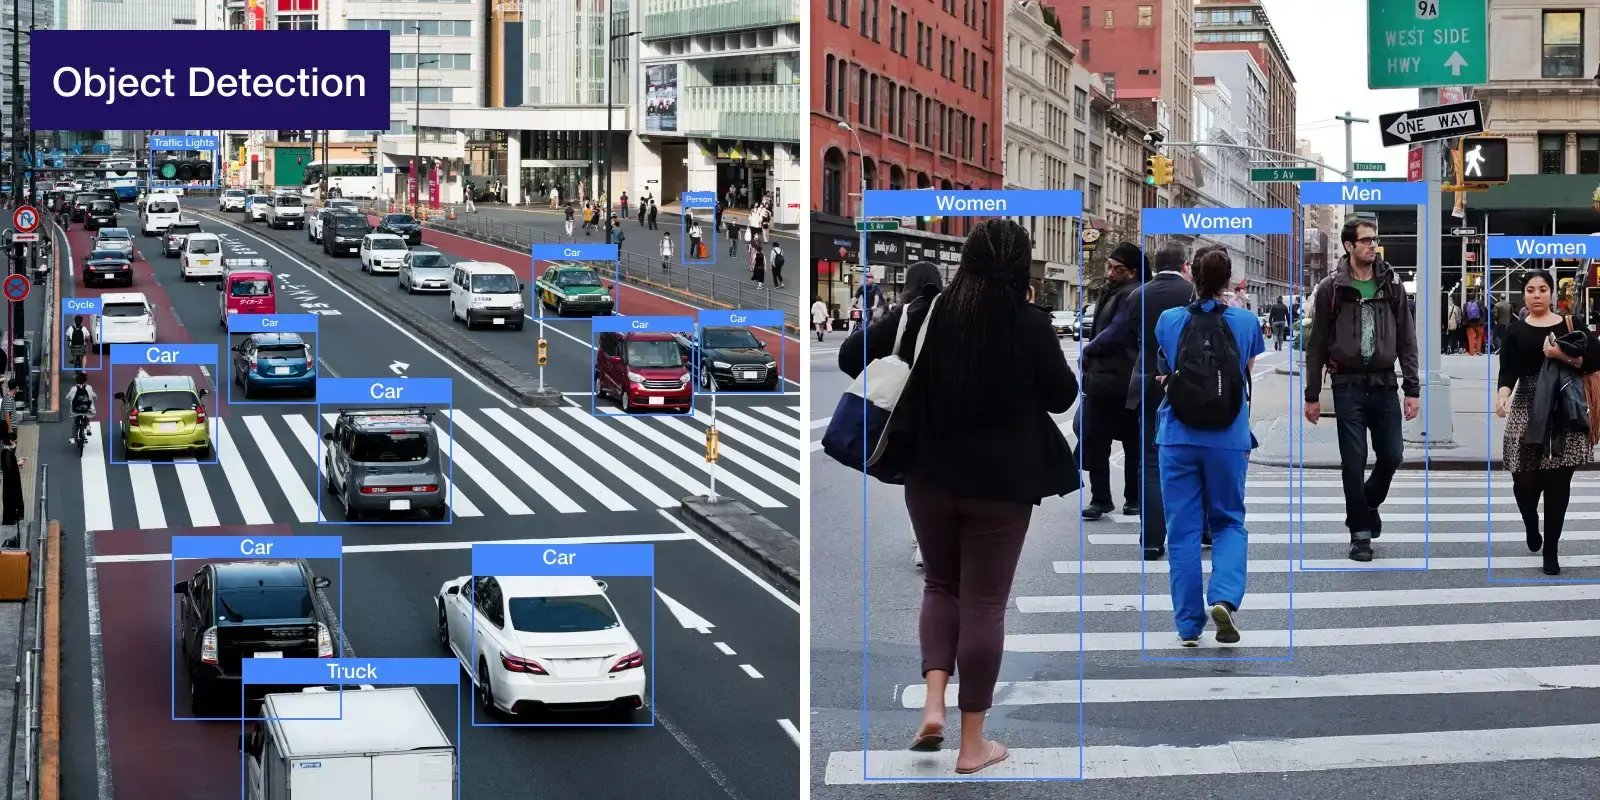
Object detection pretty much sounds like object classification, but it goes deeper than that. It finds where objects are in an image and draws a box around them. To make it a step further, object recognition deals with identifying exactly what those objects are. In simpler terms, object recognition exactly finds an object within a visual data. For example, spotting “a person” in a crowd is detection, whereas knowing the particular person who goes by the name “John” is recognition. However, it needs intensive training to function better.
- Finds multiple objects and their exact positions
- Recognition adds an identity or category to each detection
- Key in autonomous driving, retail analytics, and smart security
Object Tracking
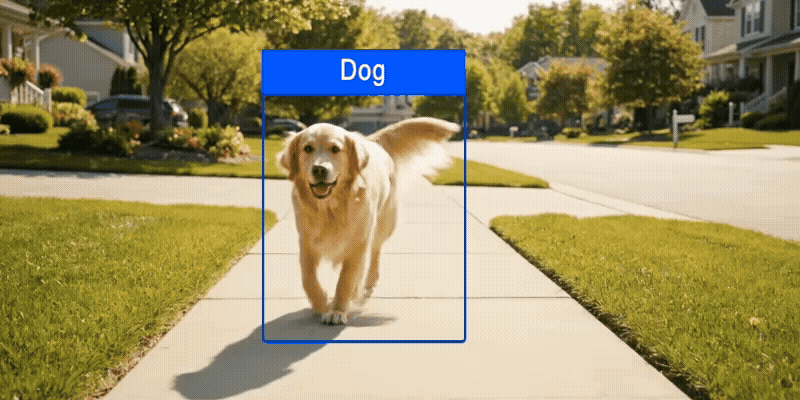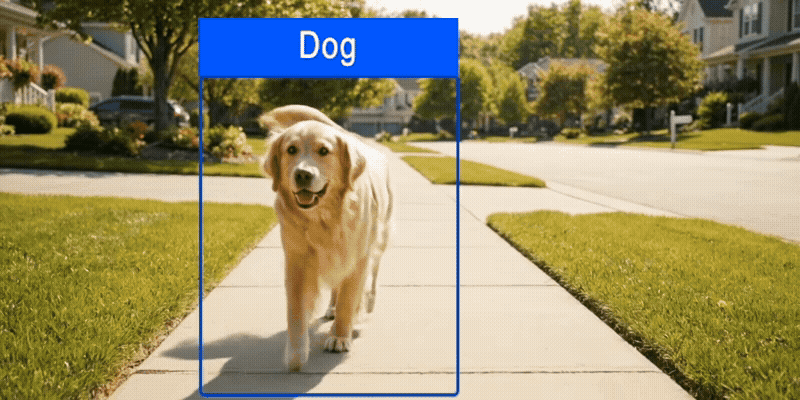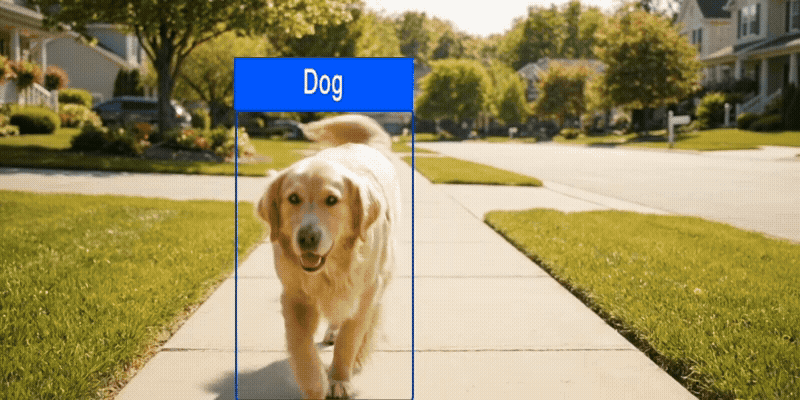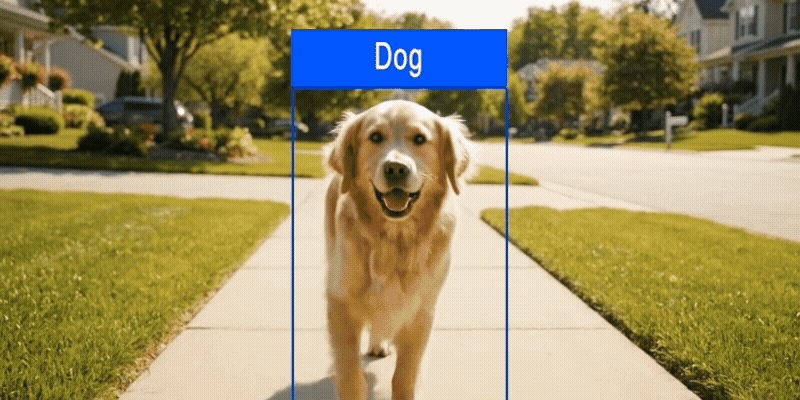
Object tracking is a detailed process of following an object across multiple frames of a video. It doesn’t just detect something once. Instead, it watches how that object moves over time. This is what mainly powers motion tracking in sports broadcasts or real-time surveillance.